Retries are capped and backed off, and every outbound call times out
grep -rn "fetch(" src/ | grep -vc "signal" # fetches with no abort signalgrep -rnE "retry| retries" src/ | grep -viE "backoff| jitter| max"
Get every Fix AI Slop Code episode
The code it wrote, the code it should have written and a check, for every episode
What is going on
Three layers each retrying three times is 27 requests for one failure. AWS's October 2025 postmortem calls the result "congestive collapse," where engineers throttled traffic by hand. Node's fetch has no useful default timeout, so a hung upstream is a function you pay for by the second.
Where it bit
Not in ours, by luck more than design. It is the retry storm, the one that multiplies, and the most expensive of the five in this group.
The practice
Retry at one layer only, capped exponential backoff with jitter, honor Retry-After. AbortSignal.timeout(5000) on every fetch, statement_timeout on Postgres, explicit maxDuration on functions. A circuit breaker for anything that can go down for an hour.
Get this check as a script you can run tonight
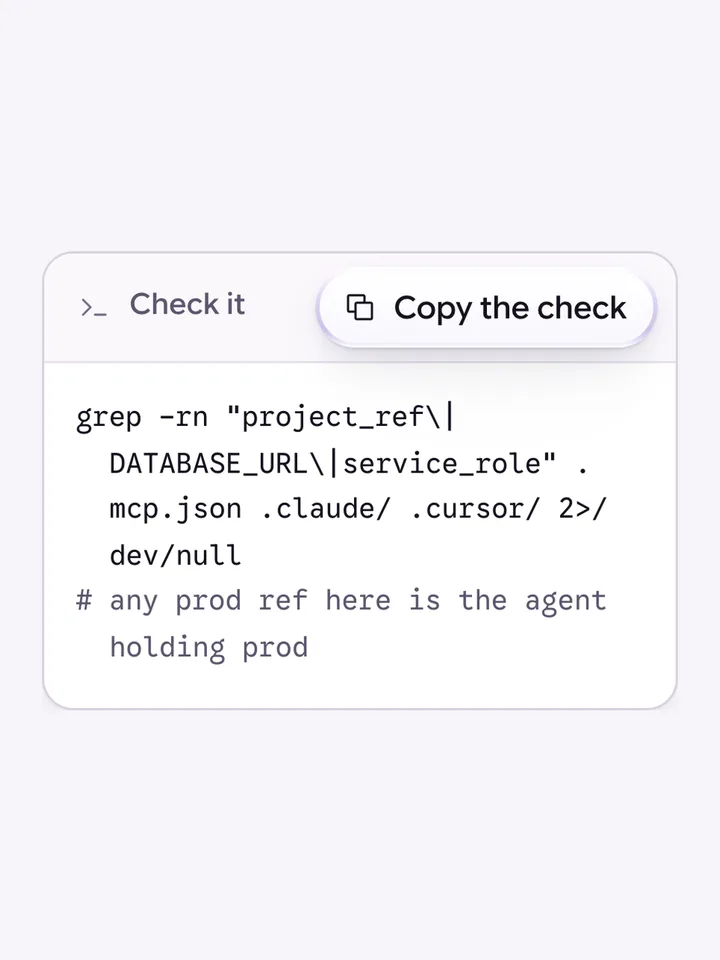
The coding agent never holds production credentials
An agent with a production database URL will sooner or later run a migration or a cleanup against it, so production secrets never enter its env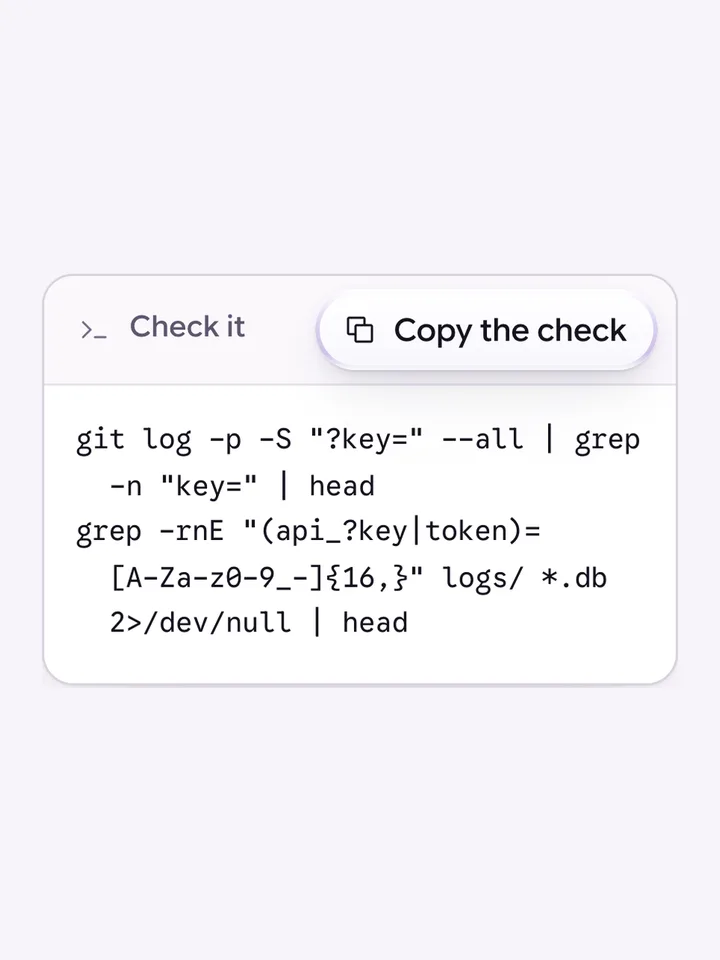
Keys go in headers, never in URLs
A URL is written to server logs, CDN logs, browser history and error trackers, so an API key in a query string is a key in five places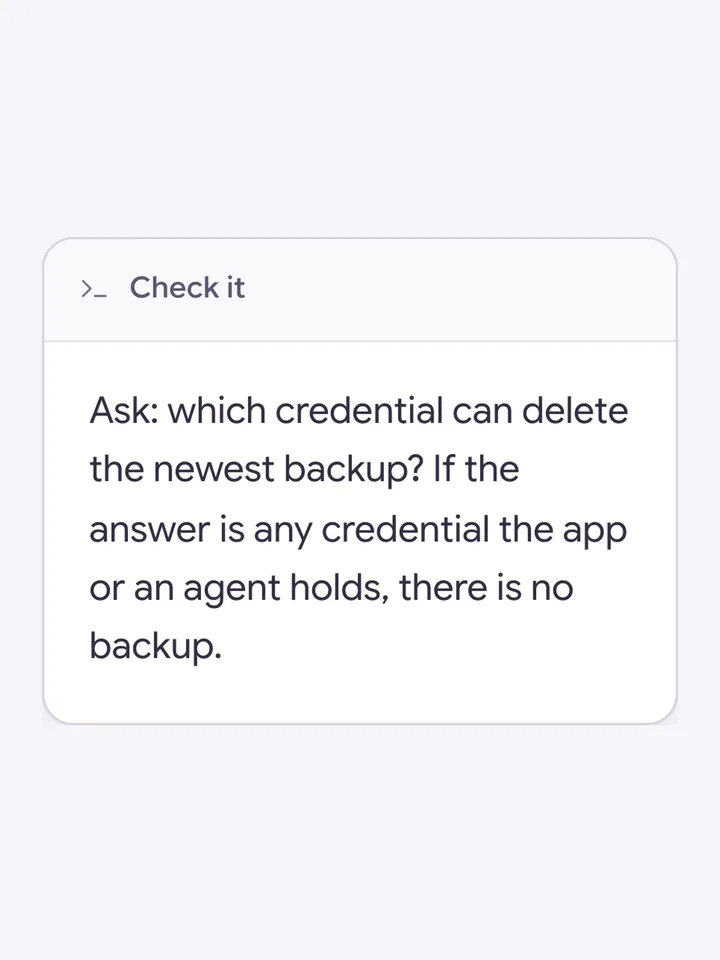
Backups the app cannot reach, and one restore you have actually done
A backup on the same account the app or an agent can delete from is not a backup, and a restore you have never run is a number you do not have
If this check came back with more than you expected, that is worth a conversation